Xiaomai is an AI in development, aiming for explainable, exploratory, autonomous reasoning evolution. Starting from an imperfect open-source model, it gradually turns its own computation, weights, runtime state and learning mechanisms into objects it can read, examine and intervene on. A human question may contain mistaken assumptions or omit constraints, so an AI can answer it as written and still produce an unwanted result. I want Xiaomai to notice that gap while working, examine the framing and propose a revised problem definition that preserves the original purpose and constraints, then test it through controlled comparisons.
I also want it to form worthwhile questions from unknowns, contradictions and imagined possibilities, and change how it represents, reasons and learns. Questioning, self-examination and experiments must connect to observable computation, assumptions and changes so their causes can be checked. The goal is new understanding that becomes lasting, reusable capabilities and gradually overcomes existing limitations.
Built so farResearch parameters in the same True model have been updated on real 9B features, saved, and continued with the next update in two fresh processes. View engineering records ↗
Current boundaryExplainable, exploratory, autonomous reasoning evolution is a development goal. A written chain of thought does not reveal all internal mechanisms; autonomous research and problem redefinition, new knowledge and lasting capability gains remain unproven. View the continuation plan ↗
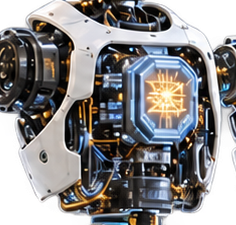
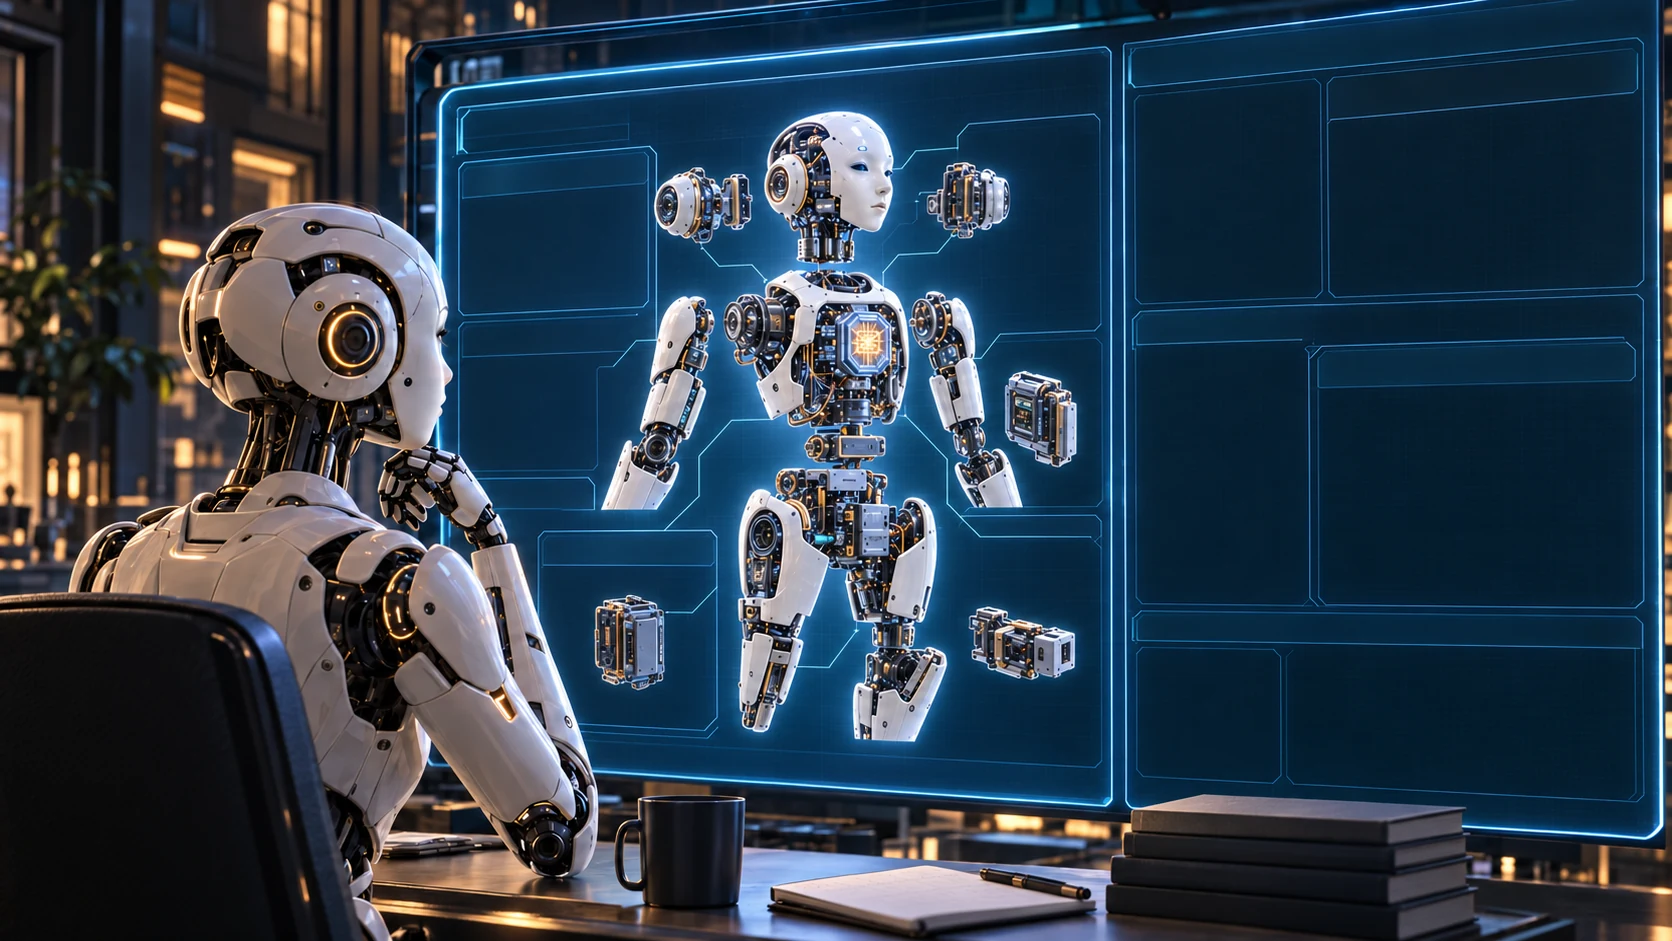
An illustrated body as a metaphor for inspecting computationConcept laboratory · Not a model measurement
CONCEPT COMPONENT01
How a relationship is representedh → prediction(h)Trace assumptions and conditions.Question the equation too
Its current representation may prevent some explanations from ever appearing.
Trace candidate paths first
Ablate, replace, restore
Imagine other possibilities
Illustrated dependency connected
Evidence required
State what each candidate predicts, then seek observations that distinguish them.
Select a component and trace its relationships.
Research paths · Interactive illustration
The tour is waiting. It resumes when this scene is visible and ambient motion is allowed.
Imagine other possibilities
Logic · Search · Probability
What could Xiaomai consider before it knows the answer?
H = {h₁, h₂, …}; prediction(hᵢ)Example representation
Xiaomai needs to trace actual computation to candidate components and dependencies first, then test them through ablation, replacement and restoration. Explainable AI should let its account be checked against evidence, including the equations, functions and applicable conditions.
01 / What to question
Its current representation may prevent some explanations from ever appearing.
Record the available evidence, imagined possibilities and unknowns separately.
02 / How to investigate
Propose different understandings and reasons to investigate them. Ask what its own methods for forming problems and generating candidates leave out.
Ablate, replace, restoreImagine other possibilities
03 / How to judge
State what each candidate predicts, then seek observations that distinguish them.
Choose controls and counterexamples for the question
The illustrated dependency is intact. No experimental score is displayed.
This is a human-authored research illustration. Each formula is an example, not an identified model equation. No Xiaomai model is called and no causes inside it are measured here; this is not a model experiment result.
The illustrated body is a metaphor for AI computation, not robot hardware. A person designed the scene, components and paths; no Xiaomai model is connected. Interaction explains the research concept, not an established ability to conduct autonomous research.
Xiaomai would examine not just how an answer was produced, but why it keeps seeing only these possibilities.
New understanding, carried into the next challenge.
A human question may contain a mistaken assumption, omit a constraint or misstate what the person wants to achieve. Even an AI that answers it as written can produce an unwanted result. Xiaomai asks whether it can notice that gap while working, examine the original problem definition and propose a revision that can be checked.
A revised definition must preserve the original purpose and constraints. If the intent is unclear, ask the person before comparing the reasoning and results under different definitions. The goal is to retain understanding checked through experiments and counterexamples, changing how the AI later questions, reasons and learns beyond a single prompt edit. Reliable performance remains unproven.
01Start where retained capabilities could matter.
Potential early beneficiaries are teams building long-running AI and researchers who repeatedly develop and test hypotheses. Candidate situations include a representation that cannot explain a new observation, or methods that people must reconstruct whenever the problem changes. Retaining and independently reusing a useful method could let later work build on earlier understanding.
These are candidate needs for interviews and trials, not confirmed customers or benefits. Collaboration starts by identifying a real, recurring limitation and agreeing what change would be useful. The broader goal extends beyond answering questions or correcting errors.
02Connect the idea to what can actually change.
Form questions from unknowns, contradictions and new possibilities, then inspect observable computation and assumptions. Where needed, redefine the problem and change an executable representation, reasoning method or learning method. Test causes through ablation and competing explanations, then check whether it independently selects effective changes after saving, restarting and encountering new problems.
Explainable AI, self-correction, autonomous research and self-modification already have substantial prior work. Xiaomai builds on it to test whether connecting problem redefinition to observable, reversible mechanism changes can accumulate more reliable capabilities. Novelty and superiority over existing methods have not been established.
Method details: inspect, test and retain a change
01Start from unknowns. Examine how inquiry works.
Find worthwhile questions in contradictions, gaps in understanding or imagined possibilities. Xiaomai should notice problems without waiting to be told it is wrong, and assess others' corrections against evidence.
Metacognition goes further: why choose this question, experiment or way of learning? If the method misses a clue, revise and test the method itself. Inquiry can branch, revisit or roll back.
02Check explanations against actual computation.
Explainable AI is a starting point: explanations must be checked against observable computation. Neither a written chain of thought nor a local observation reveals complete internal reasoning. Trace inputs, representations, computation and outputs to identify candidate components and dependencies, then investigate causality through ablation, replacement, restoration and controls. A difference from one ablation is only a clue; alternative explanations and interactions still need testing.
Reason from first principles through the equations, functions, variables, assumptions and conditions of basic disciplines. Python is currently a temporary execution and inspection tool; the longer-term research asks how to represent and modify these relationships. This does not mean every discipline can be fully formalized. What cannot yet be observed or represented remains unknown.
03Turn new understanding into a change that runs.
Every calculation can be correct while the result still fails to explain an observation. Revisit the problem representation, missing variables and assumptions; turn a new understanding into an executable mechanism with predictions that distinguish it from the old one. Preserve the original requirement and constraints when redefining the problem. Ask the person if intent is unclear; the AI must not assume it knows what they really want. Detecting every framing error is not guaranteed.
Test a new explanation against external observations, controlled experiments and counterexamples. It must be possible to refute it and roll back a change before there is a basis for judging whether it adds new knowledge.
04Select and reuse the change after a restart.
Save effective changes, then test whether Xiaomai selects and reuses them after a restart, on new questions and under conditions held out from tuning. Check existing capabilities for regressions and restore an older version when needed. Saving notes or parameters covers only one step; lasting capability after restart and on new questions remains unverified.
Connecting these four capabilities remains a research goal to test. The next collaboration should jointly define a scoped research question, mechanisms we can inspect, conditions that would refute the explanation and checks on reuse after saving.
See the method with 3 + 5: trace candidates, then test by ablation
Asked to add. Why did it multiply?
Question3 + 5 = ?Wrong output3 × 5 = 15
This hypothetical example explains the method. It is not a measured Xiaomai result or the selected next experiment.
A model might write a detailed chain of thought and still get this wrong. Check its explanation against what actually ran: where was the plus sign recognized, where was the operation selected, and how was the final text produced?
Trace the input, representations, computation and output to identify candidate components and paths. Functions may be distributed across interacting parts; we cannot assume a single component controls addition or multiplication.
Identify candidates, then run ablation experiments. Remove, replace or restore a suspected part. Does addition recover? Is valid multiplication damaged? Does the intervention help explain the cause, or merely disable computation? Interactions between components may need testing too.
The purpose stays fixed: calculate 3 + 5. What may need revising is the model's understanding of the symbol, task or mechanism. Changing the person's request to multiplication would not solve it.
Prior work and fair comparisons
Prior work spans mechanism observation through persistent self-modification. These original sources establish their scope; one failure case cannot stand for an entire method.
Later comparisons would retain each method's memory, reflection, search and saved improvements, using the same base model and initial state with comparable information, tools and total budgets. Observation, intervention, training, saving and restoration all count toward cost. Mechanism removal and equal-cost alternatives would face held-out problems, restart and regression checks. This is a research proposal, not an executed comparison.
Explore the research process: from possibilities to retained changes
This human-authored concept illustration does not call a model or run experiments. Select a stage to explore its questions. Inquiry can revisit, branch or roll back.
From a suspect component to an assumption worth revisiting.
First trace actual computation to candidate paths, then test the role of each part. Which equations and functions does a component use? Do its assumptions still hold for this problem?
Inspect mechanisms and assumptions · Concept illustration
Use the stages above to see what each part of the inquiry asks and what evidence it needs. This illustration is human-authored and is not connected to a model.
Imagine different possibilitiesWhat this step investigates
Imagine other possibilities
What could Xiaomai consider before it knows the answer?
H = {h₁, h₂, …}; prediction(hᵢ)A representation to investigate
An assumption to question
Its current representation may prevent some explanations from ever appearing.
Conditions to establish
Record the available evidence, imagined possibilities and unknowns separately.
What to check next
State what each candidate predicts, then seek observations that distinguish them.
Next, compare the candidate explanations: what does each predict, and which control could distinguish them? If none holds up, revisit how the problem was defined.
Which relationships sit behind the question?
You choose the path here. AI choosing its own research question remains a goal to test.
Relationship under inquiryRevisit, refutation or unknownsOther conceptual relationships
A person authored these relationships and candidates. This does not call a model or produce a new mechanism or experimental result. Selecting a body component and selecting an inquiry stage are different actions; this diagram follows the inquiry stage and branch.
Xiaomai would not have to wait for a wrong answer.
Xiaomai would imagine other possibilities: a function that does not yet exist, an unexplained observation or another way to understand a problem. Could it turn its own unknowns and gaps in understanding into worthwhile research questions, explain why they matter, and explore beyond questions it already knows how to answer?
If a premise changes, what other possibilities could Xiaomai see?
Evidence needed
Retain candidates, reasons for selecting questions and distinguishable predictions. Keep untestable possibilities explicitly unknown.
Select a stage above, revisit the definition or explore another candidate.
Through October 25, an older native 9B CPU checkpoint has been restored and unchanged state saved. Research and updates were not reached; the new artifact has not been cold-loaded, and the strict source-inventory check failed. Separate small-model checks from October 23 cover update feedback, rollback after actual writes, replay and same-source cold restoration. Complete native research updates and formal migration remain unaccepted.
In the earlier engineering baseline, 25 research parameter tensors in the same True model have been updated and saved. Two fresh processes resumed the next research update from the designated checkpoint. The checked 206 state and gradient records, containing 3,108,565 values, matched bit for bit. This helps future experiments check whether a change entered the research parameters and survived saving and continuation; it does not imply matching other outputs or full text generation.
The ECC v2 external read-only assistant supplied more complete facts on four exposed source-reading tasks, at increased cost. Extra and interrupted cases remain separate. It did not load native Xiaomai custom state or the learner and does not establish native restoration or autonomy. The earlier three-arm CPU comparison did not confirm a full-system advantage; bounded A100 updates from October 18 retain their earlier scope. This weekly issue records the individual results and limitations.
The goal is explainable, exploratory, autonomous reasoning evolution, including autonomously forming and redefining problems. Xiaomai gradually reads and examines its own computation, weights, runtime state and learning mechanisms; explores the unknown world and itself; forms problems from contradictions; proposes new concepts, representations or methods; tests them through derivation, counterexamples and interventions; branches or backtracks based on results; keeps effective changes; and checks whether new knowledge and capabilities keep working after restarts and in unseen situations. These abilities remain unverified.
Scope and limitationsLocal proposals, measurements and operations have been recorded. Each of these — stable autonomous problem redefinition, new knowledge and lasting capabilities — still requires independent testing. Computation tests, parameter updates, numerical agreement or successful saving cannot substitute for that evidence.
Next, complete the source-inventory checks and cold restoration of the new artifact, then reach native research and the next update. Understanding diagnostics, autonomous problem formation and selecting saved revisions in new situations still need controlled research tasks. New knowledge and lasting capability remain unproven.
An older checkpoint is restored and saved, without reaching research updates
A streaming-fingerprint candidate restored an older 41-record native 9B checkpoint on CPU and saved unchanged state. This adds bounded restore-and-save evidence; the original checkpoint and source remain unchanged. The new saved artifact has a source inventory of 104, down from 115.
Scope and limitationsBoth research and update are NOT_REACHED; the new artifact has not been cold-loaded. only_expected_source_migrated=false and the strict source-inventory check failed. This is not restoration of the latest CUDA checkpoint, complete source migration or a complete research/update/save cycle.
Show the source basis
2026-W43 research update and public item-level index: https://xiaomailab.com/weekly-evidence-2026-W43.json
Record date
Version / scope
ECC v2 / external read-only research assistant
Descriptive comparison on exposed development cases
Retrieval repair fills more facts across 4 tasks at increased cost
Across 4 exposed source-reading tasks using an external Ornith research assistant, full correctness changed from 0/4 to 1/4 and complete factual items from 1/12 to 7/12. The new method used more time and tokens. Another 81 extra or interrupted cases remain separate and are excluded from the quality denominator.
Scope and limitationsThis is a descriptive comparison after reducing the original protocol, not 8 cases preregistered in advance. Prompts, snippets and schema changed together, so it cannot isolate one repair or establish general capability improvement. The external assistant did not load native Xiaomai custom state or the learner; it is not evidence for native restoration or autonomous research.
Show the source basis
2026-W43 research update and public item-level index: https://xiaomailab.com/weekly-evidence-2026-W43.json
Record date
Version / scope
CPU update diagnostics and recovery
Bounded CPU engineering acceptance
Return update outcomes to the next inquiry and recover them after saving
Successful updates, failures and observation errors after commit are recorded separately and enter the next research input. The declared CPU scope checks rollback after actual writes, replay without duplicate updates and same-source cold restoration in a fresh process. With observation on and off, 64 events and 6,082 FP32 values match the control raw bytes.
Scope and limitationsThis covers specified small models, states and observation boundaries. Formal migration of old 9B checkpoints, the first gradient fault across a complete decoder and CUDA remain unaccepted. It does not demonstrate understanding diagnostics, autonomous repair or lasting improvement on unseen problems.
Show the source basis
2026-W43 research update and public item-level index: https://xiaomailab.com/weekly-evidence-2026-W43.json
Show 14 earlier records
Record date
Version / scope
Three CPU arms; delivered 2026-10-22
No confirmed full-system advantage
Keep the comparison without a clear advantage and refine the capability question
The three-arm CPU comparison did not confirm an advantage for the complete system; all arms made 0 formal parameter updates. Original failures and comparison results are retained. These tasks mainly involved one-shot program solving, which differs from a research loop that forms problems, distinguishes hypotheses and saves methods.
Scope and limitationsThis result does not support a claim of autonomous lasting improvement, nor establish that memory or update mechanisms are generally ineffective. Autonomous problem redefinition, selecting saved revisions in new situations and benefits across problems still need suitable independent controls.
Show the source basis
2026-W43 research update; comparison results and delivery from 2026-10-22. Item-level index: https://xiaomailab.com/weekly-evidence-2026-W43.json
Historical addition: selected-parameter updates, fresh-process continuation and saving
An earlier A100 experiment completed two actual updates within 47 selected parameter groups of a 9B-class model. A fresh process exactly restored the selected state from the first save, then performed the second update and saved again. These existing 2026-10-18 results are only added to the progress index in this issue.
Scope and limitationsThe host specified the input and target; the model did not propose them. This is not training all 9B parameters, general numerical equivalence or complete migration across environments. A third process has not reloaded the second checkpoint, and this weekly update did not rerun the experiment.
Show the source basis
2026-W42 research update and public item-level index: https://xiaomailab.com/weekly-evidence-2026-W42.json
Record date
Version / scope
Core research
Not yet demonstrated
Finding what is worth questioning without being told
The goal is explainable, exploratory, autonomous reasoning evolution, including autonomously forming and redefining problems. Xiaomai gradually reads and examines its own computation, weights, runtime state and learning mechanisms; explores the unknown world and itself; forms problems from contradictions; proposes new concepts, representations or methods; tests them through derivation, counterexamples and interventions; branches or backtracks based on results; keeps effective changes; and checks whether new knowledge and capabilities keep working after restarts and in unseen situations. These abilities remain unverified.
Scope and limitationsLocal proposals, measurements and operations have been recorded. Each of these — stable autonomous problem redefinition, new knowledge and lasting capabilities — still requires independent testing. Computation tests, parameter updates, numerical agreement or successful saving cannot substitute for that evidence.
Show the source basis
Research positioning (updated 2026-10-10); the R15 method loop had not passed capability acceptance as of 2026-10-09; v0.9.2 autonomous_research_improvement_proven=false
Record date
Version / scope
R19 formal entry step8
Bounded continuation acceptance
After saving, two fresh processes continue with the same next step
From the research checkpoint designated as the formal entry, two independent fresh processes each ran the next original research update. According to the original comparison receipt, 206 typed numerical records with dtype and shape (181 saved-state records and 25 fresh-gradient records), totalling 3,108,565 scalar values, matched bit for bit. The same day, the A100 project, checkpoints and runtime environment were archived at a pause point.
Scope and limitationsThis is engineering evidence for saving and continuation. It does not show equivalence of arbitrary outputs or text generation, nor that new concepts, knowledge or lasting capabilities have formed; the next checkpoint was not automatically promoted to the formal entry. Still unfinished that day: full-parameter equivalence for five new operators, full acceptance with tracing on, Python forward/backward and updates for the 9B base, the complete text chain, and capability acceptance for the R15 method loop.
Probability operators join the same traceable backward computation
Forward and backward passes for exp, log, softmax, log_softmax, logsumexp and rsub share one Python Tape. Across three synthetic initializations with 177 parameter elements, results matched native autograd with the same PythonAdamW within the preset tolerance (maximum difference about 1.2e-7). Tracing on and off produced bit-identical results, and six fresh processes that loaded saved values computed a bit-identical second step.
Scope and limitationsAll tests are synthetic and CPU-only; this is not an update acceptance for the 25 real research tensors. No new True update, GPU run or 9B backward pass was performed, and the private observation entry point was not connected.
A research update on real 9B features, saved and cold-restored
The frozen 9B model computed features on the GPU. The research transaction then ran backward through the original Tape, updated with the original AdamW and saved; 25 research parameter tensors changed. Native and tracing-off paths were compared across 207 records and 3,108,566 values, all within the preset tolerance (maximum difference about 3e-8; 81 records were not bit-identical). Each of the two checkpoints was cold-restored in a fresh process, and the CPU research state (181 records, 2,960,497 values) matched the saved state bit for bit.
Scope and limitationsThe cold restore covers CPU research state only; it excludes full CUDA random-state restoration and all lazily loaded base values, and no next transaction was run. The tracing-on run was stopped by the coordinator and did not pass. In R15, real model generation wrote numbers as strings and the original parser rejected the output, so no method was saved. This is not a full 9B backward pass.
Full 32-layer forward passes run, but the candidate kernel does not yet match
On an A100, the original and the Python candidate each completed two full 32-layer feature forward passes, with all 24 GDN layers routed through the candidate kernel. The outer computation ran on CUDA; the candidate GDN kernel was a compiled CPU implementation.
Scope and limitationsThe fixed numerical tolerance check between the original and the rewrite did not pass. The boundary has been located at the first-layer kernel, where identical inputs give different outputs; the exact arithmetic cause is still under investigation. R10 and R11 from the same period were CPU-only bounded acceptances. This batch did not complete acceptance for text generation, new gradients, updates, saving or fresh-process continuation.
Show the source basis
R12 A100 execution and acceptance records; R11 bounded acceptance record (2026-10-04, not yet published)
Record date
Version / scope
Six CPU engineering workstreams
Bounded engineering acceptance
Extending checks on readable weights and local research computation
Six CPU workstreams passed 163 tests and 12 subtests. One complete, real 8 MiB BF16 weight tensor passed readable export, restoration, a specified edit and Python projection. Small chunk backward computation, numerical tracing and routing through the original GDN object were separately validated with synthetic data.
Scope and limitationsThe optimizer check replays existing real records; this batch did not update True or use a GPU. Full weight conversion and full-size chunks remain unfinished. Restoration checks accepted data custody, but runtime requirements remain unmet.
Show the source basis
Six CPU workstreams: STATUS.json, PACKAGE_RECHECK.json and PUBLICATION_RECEIPT.json; research/cpu-gpu-readiness-20261001, commit e2c14b2a
Record date
Version / scope
True / Python research backend
Real update and continuation acceptance
The same True model: update, save and continue in fresh processes
The original research credit transaction was connected to PythonTape and PythonAdamW. It updated and saved 25 research parameter tensors. After saving, two fresh processes continued with the next update; outputs, parameters, master weights, momentum and CPU random state matched bit for bit.
Scope and limitationsThe frozen 32-layer text feature computation still used native CUDA. Research arithmetic, backward computation and the optimizer used Python on CPU in FP32. This validates bounded engineering continuity, not a complete Python model, full GPU training or autonomous research capability.
Show the source basis
True Python research backend: independent acceptance records for native/Python comparison, update and saving, and fresh-process continuation; research/a100-true-python-backend-20260930, commit 2ce8fcd5
Record date
Version / scope
True / A100 read-only
Read-only import validation
Importing selected states from the real True model
The same True model was restored on an A100. Read-only checks covered 47 master-weight states and 20 existing momentum states, containing 1,067,974 selected parameter values.
Scope and limitationsThis read-only batch included no forward pass, loss, gradient update or new saved state. It accepted state import only; later updates and continuation are reported in newer records.
Show the source basis
next_learning_v1 INDEPENDENT_ACCEPTANCE.json
Record date
Version / scope
v0.9.4
Summary record / limited comparison
Comparing the GDN core of the real layer 0
The README records a 2-token prefill, 1-token continuation decode and 6 gradient comparisons.
Scope and limitationsThis version still used native PyTorch for the outer linear projections. The record covers a local core comparison; full-model integration was not accepted in this batch.
Show the source basis
v0.9.4 README_zh.md / acceptance scope
Record date
Version / scope
v0.9.4
Synthetic trial
Connecting modification, learning and restoration
The README records a trial with 456 synthetic parameters connecting Python backward computation, AdamW, saving and restoration in a new process.
Scope and limitationsThis version's synthetic trial did not validate real True learning. Later real-model updates and continuation have separate records; synthetic results cannot replace them.
Show the source basis
v0.9.4 README_zh.md / acceptance scope
Record date
Version / scope
v0.9.2
Limited validation
A regression baseline for CPU learning transactions
The delivery summary records 4,555 CPU regression tests, with 0 failures, 0 errors and 0 skipped tests.
Scope and limitationsThe credit loss remains a synthetic contract. Passing tests covers only this CPU transaction scope.
Continue with the same True model. Take the research further.
True is the model system used and developed for Xiaomai. Its research parameters have been updated, saved and continued in fresh processes; six CPU workstreams also have code and validation records. The next step builds on this starting point: make changes within the same model traceable, reversible and saveable, then test whether new representations, reasoning and learning methods become lasting capabilities.
Verify sources and environment before running True.
The latest checkpoint's stored data has passed its checks, but the current Windows and PyTorch environment differs from the validated environment, and a full cold restore of the latest integrated delivery remains incomplete. Continuing True requires a matching environment or an explicitly validated migration. Independently testable CPU work can continue.
1
Extend the verified update path
Connect the reversible optimizer boundary to the same True update path. Use the same source, saved starting state and input to compare updates before and after integration. Deliver checks of numerical results, parameters and learning state, stage timings, and fresh-process continuation after saving, against the existing criteria. The boundary has passed a replay of recorded real updates; integration acceptance remains pending.
To integrate
2
Reach actual model dimensions
Extend the new chunk backward path and full-input processing (prefill) from small validated cases to actual model dimensions, addressing capacity and segmented recomputation. Check the routing on CPU, then integrate the corresponding GPU forward and backward paths with explicit device and precision rules. Hardware validation follows an executable candidate.
To extend
3
Make changes traceable and recoverable
Build on the existing numerical traces, readable weights and recovery checks to expand which computations can be observed and changed. Continue the full weight conversion, operator coverage and detailed tracing, then assemble the same True system's sources, assets and latest state for a verified restore in a clean process.
To continue
Engineering deliverables and later capability criteria
Each step should leave a result others can check.
Before-and-after comparisons
Fix the sources, inputs and existing state, then record the computation path, numerical differences and stage timings. Apply the tolerance or bitwise comparison specified for each check; a component pass does not establish whole-model success.
Observe and undo changes
Identify what can be recorded, edited or only read, and what remains unobserved. Check that tracing neither omits events nor changes results. Keep version differences, failure conditions and a way to undo each adapter or mechanism change.
Continue after saving
Verify saved state together with its sources and environment, restore it in a fresh process and perform the next update. Continuing saved state and retaining a reusable new capability require separate validation.
Once the system connects, research ability still needs testing.
Building on the earlier problem-formation studies and failure records, I want to test whether Xiaomai can identify its own unknowns, question an existing definition, change its understanding through falsifiable experiments and retain the new method. Passing engineering checks has not established these abilities.
Find a question worth investigating
Form questions from its own unknowns, contradictions or imagined possibilities without being told where the gap is. Examine why it chose that question, experiment and way of learning.
Make redefinition executable
Keep the original purpose clear while changing the representation, variables, dependencies or mechanism, leaving an executable difference. Accept well-supported refutations; when a correction is wrong or unsupported, reject the change and preserve what already works.
Distinguish explanations through intervention
Trace actual inputs, functions, state and outputs to identify candidate causes, then choose replacements or ablations that test dependencies and interactions. A complete written account or a single ablation difference is not enough to establish every root cause.
Restart, change the problem, test again
Save, stop the process and reload. On held-out conditions and related problems, observe whether it independently reuses the new method and whether existing abilities regress. If the effect disappears or causes a regression, retain the result and withdraw the corresponding changes and claims.
Show the proposed comparison framework (A–D)
This is a possible framework for later capability tests, not a finalized or executed experiment. Its environment, candidate mechanism and interpretation criteria must follow the existing research records and what the system can actually run. It does not replace the engineering sequence above.
A
Direct response
Establish how the same model would ordinarily approach the problem.
Proposed
B
Additional reflection
Allow reflection and revision, recording the effect and cost of further attempts.
Proposed
C
Candidate mechanism
Select a mechanism for forming questions, choosing experiments or changing methods within the paths that are actually integrated and observable.
Proposed
D
Ablate candidate causes
Form competing explanations first, then remove or replace specified mechanisms in C and examine their interactions.
Proposed
Use the same base model and initial state with comparable information, tools and total budgets. Baselines retain memory, reflection, search and saved improvements; observation, intervention, training, saving, restoration and validation all count toward cost. Agree on held-out situations, repeat counts and refutation criteria in advance, including equal-cost alternatives. Narrow or withdraw claims if the mechanism adds nothing beyond reflection, removing it leaves results unchanged, or its effect fails after restart or transfer.
Start with a piece of work we can deliver.
I would like to start discussions with research or systems teams that have an executable model and a recurring failure, and with partners who can take on the engineering and reproduction work below. True updates, save-and-resume and six CPU workstreams already have source, tests and acceptance records. A first message can identify a limitation to improve, materials to review and work you could contribute.
Systems, numerical methods and GPU integration
Bring numerical or GPU engineering experience to the existing True update process and six CPU workstreams, extending chunked computation to actual model dimensions. Return timing breakdowns, gradient and numerical comparisons, and evidence of updates, saving and fresh-process continuation after integration.
Observation and explainability
Bring tracing or experimental-design experience. Extend the existing numerical records, checking for omissions and whether observation changes the result before selecting candidates for intervention and control comparisons. Return observation boundaries, comparison results and explanations that remain unresolved.
Research methods and lasting changes
Bring domain questions or counterexamples to the existing problem-formation and refutation requirements. Test autonomous questioning, executable reframing that preserves the original requirement, and transfer after saving. Return candidates, refutations, failures and results on unseen situations.
Source verification and independent reproduction
Bring a reproducible environment or verification experience to check the existing source, receipts and checkpoint. After environment matching or migration comparisons pass, perform a fresh-process cold restore. Return source and runtime provenance, restoration discrepancies and blockers.
The website currently provides public progress summaries and a research brief. First review the scope of existing deliveries, then agree on access to source, receipts and real assets that require authorization. Public progress · Research brief
I graduated in Computer Science and Information Engineering from National University of Kaohsiung and am developing Xiaomai independently.
Tie the next investment of resources to a clear result.
Resource needs follow the existing True baseline and six CPU deliveries. Confirm the source, environment, remaining work and deliverables before estimating equipment, compute, funding and time. Independent CPU work can proceed first; GPU rental depends on integration readiness.
Match the environment and verify source
Environment and reproduction support help verify fixed source, checkpoint and runtime dependencies. Deliver environment-matching or migration-comparison records. The current True model is loaded only after execution prerequisites pass.
Extend CPU capacity and observation
Engineering support and research funding advance full-size chunked computation, numerical boundaries, weight and operator coverage, and detailed tracing. Deliver capacity, gradient, per-value and save-transaction comparisons, retaining failures and uncovered areas.
GPU integration and a new cold restore
Prepare an executable candidate that integrates GPU forward and backward computation into the same update process, with numerical criteria and rollback, before arranging hardware acceptance. Deliver performance and numerical comparisons, update-and-save records and cold-restore evidence for the new complete delivery.
Research support can fund agreed resources, deliverables, credit and publication scope; findings may reject the hypothesis. Investment discussions also need to examine candidate demand, durable value, rights and commercial terms. Engineering acceptance does not establish a market. The zeczec proposal is under review, scheduled for October 19, 2026 at 12:00 through December 18 at 00:00, Taiwan time, subject to platform approval. Fundraising has not yet launched and payments have not launched. Research collaboration remains available by email.
During the six-month development period, the plan calls for weekly public development logs, one integrated result per month, and six monthly plain-language summaries, each emailed and published. A results index follows at closeout. Development is provisionally scheduled for February–July 2027, with closing materials in August, conditional on successful funding and funds and the compute resources needed to start development being ready by the end of January. Current logs are prelaunch development records.
These optional illustrations explain a minimal principle. A person designed the arithmetic and controllers, and they execute in the browser. They are not Xiaomai's autonomous research results or observations of a complete model's internals.
Minimal example: request, routing and arithmetic
Xiaomai's research direction · A human-designed interactive illustration
Open the mechanism. Find where it goes wrong.
Not another answer in different words: trace an actual execution, isolate a questionable component, challenge how it was defined, then put the modification back into the computation.
Long term, we aim to use foundational equations and functions across basic disciplines to represent, inspect and modify Xiaomai's own mechanisms and understanding of problems. The achievable scope remains to be tested.
Every mechanism, modification and criterion below was written by a person in advance. No Xiaomai model is called. This lets you inspect a path; it does not claim Xiaomai has followed it autonomously.
01
Requirement
3 + 5
Sum or product is part of the request.
02
Operator resolver
(left, right) → product
The old definition receives only the number pair and ignores intent.
03
Actual arithmetic
3 × 5 = 15
Multiplication itself is correct; selecting it for this sum violates the request.
Reference for the request8
Current mechanism's output15
The result conflicts with the request. Inspect selection and execution before asking for another answer.
1. Observe a mismatch
The current explicit request is 3 + 5, with reference value 8. The original ignores operation and always selects multiplication: 3 × 5 = 15. The original conflicts with this request; inspect the route from intent to operator.
The original is currently loaded; its output is 15 and conflicts with the request. The reference and criterion come from the explicit request and human-written arithmetic, not a discovery by the model.
The issue is not simply a wrong answer. How was the request represented? Which component selected the operation? Did the selected arithmetic execute correctly according to its definition?
Changing an operator solves this example. It does not establish a change in the mechanism that forms problems, autonomous evolution, or new science. Xiaomai's research must test whether it can itself find a questionable definition, propose an executable change, and retain effective capability under fair, unprompted and restart checks.
Rethink the question, not just the answer.
Imagine a different self, then ask why its components were defined that way. A modification must be executable and open to refutation; only supported changes deserve to be retained.
Imagine different possibilities: this is a capability Xiaomai aims to investigate, not a result established by this illustration.Explore the full research cycle
Check the illustration's representation, conditions and limitations
This page uses an explicit operation and bounded numerical values to illustrate request representation, operator selection, arithmetic and a human-written reference check. sum = left + right; product = left × right. It covers only these human-written functions, not language understanding, neurons, real-model learning or complete internal thinking.
Python is currently a tool for execution and inspection. The long-term aim is to use foundational equations, functions, basic assumptions, applicability conditions and dependencies across basic disciplines to progressively represent, inspect and modify Xiaomai's own mechanisms and understanding of problems. The achievable scope of representation and modification remains unknown. This does not mean every discipline can be fully expressed as equations, that the real model has been completely decomposed, or that a root cause is guaranteed to be found.
This website illustration executes in the browser in TypeScript. Reloading an in-memory version is different from saving knowledge or parameters, restarting a real model, transferring to hidden new problems, or retaining a lasting capability improvement.
Open the operator. Inspect what was requested, too.
Inspect the same 3 and 5 through execution, equations and the request. Multiplication can be correct while the route answers the wrong question. This is a public illustration written in advance by a person, not internal source code extracted from a real model.
Inspect the same fixed sum request
sum(3, 5); the human-defined expectation is 8. All three views share this request. The product control changes only operation; the numbers and both operator formulas stay the same.
Call the function and retain the route.
This page calls executeInspection and reads its outputs and traces. The original route ignores the sum request and selects multiplication; the candidate uses an explicit operation to select the operator. The code executes in TypeScript. Its requests, candidate and assessment rules are all written in advance by a person.
The records below are returned by these illustrative function calls. They are execution records from the example, not an invented run or a model's thinking process.
The original route calculates 3 × 5 = 15 correctly, but the request is for a sum. The candidate does not hard-code 8: a product request still executes multiplication. Ablating the single routing replacement returns to fixed multiplication and reproduces the sum error. These conclusions cover only this human-written program and the specified conditions.
Both formulas are correct; the request-to-formula mapping differs.
Addition operatorsum(x, y) = x + y
Multiplication operatorproduct(x, y) = x × y
The two operators and numbers do not change. The original resolver omits the requested operation from its input and always routes to product. The candidate includes operation as its basis for choosing sum or product. The dependency from meaning to execution changes, not the multiplication formula.
Original input representation
(left, right)
Original routing rule
resolve(left, right) → product
Candidate input representation
(left, right, operation)
Candidate routing rule
resolve(left, right, operation) → operation
A person has explicitly labelled sum and product in this example. How a reliable request is obtained, whether the original problem is sound and whether ambiguous meaning is understood correctly require separate checks. A formula or route does not resolve those questions.
Retain the human-provided setup and the unknowns.
The original purpose is still to calculate the requested operation on the same numbers. Changing a sum request into a product request or displaying 8 alone does not demonstrate autonomous problem solving. This example shows how an external observer can inspect a public operator route.
The numbers 3 and 5, the meanings of sum and product, and the expectation rules are provided by a person in advance.
The faulty original route, candidate resolver and ablation are written in advance by a person. A model does not generate or modify them.
The trace records only this public function's request, routing, arithmetic and comparison. It does not observe a complete model's internal mechanisms.
What remains unknown
Can the model itself find what is worth questioning?
A person has already disclosed the sum request and fault location here. This does not validate Xiaomai autonomously finding a contradiction without a cause hint, identifying a flaw in the original problem itself or proposing a new executable definition.
What about a new problem or changing its own learning method?
This fixed illustration does not validate model learning, weight updates, fresh-process restoration or selection without prompting. Whether Xiaomai can modify and independently validate its own problem formation, experiment selection and learning mechanisms remains a long-term goal.
Does expressing it as equations reveal the root cause?
No. Equations, conditions of applicability, the source of a request, representations and mechanisms for forming problems can themselves be questioned. We do not assume that every discipline can be fully expressed as equations.
Make the limits of observation explicit.
Model self-report
This illustration does not call a model, so it contains no model self-report. Self-reports in general are not evidence of internal computation.
Observed execution
An external observer can check this human-written function's request, selected operator, actual output and trace. Observation covers only the public operator route.
Internal mechanisms not covered
This does not make Xiaomai's complete internal computations, problem formation, self-learning or lasting capability changes observable or verified.
Another illustration: temperature control and pending commands
Change one assumption: how does the prediction change?
A heating command is still on its way, yet the current temperature already determines the next action. This temperature-control illustration compares a state containing only the present temperature with one that also represents pending commands.
Human-designed educational illustration
Both controllers are designed in advance by a human, and the delay is explicitly disclosed. This does not call the Xiaomai model and is not evidence of autonomous discovery or a result from the four-group research experiment.
How many steps until a command takes effect?
The original purpose stays the same: bring the temperature close to 35°C. Adjust the command delay and observe two curves in the same environment.
Immediate effect8-step delay
120 time steps, the same initial state, and the same command limits. Drag or use the arrow keys to adjust; download the values for every step below.
Controller A: present temperature onlyController B: include pending commands
Controller A mean absolute error7.82 °C
Controller B mean absolute error0.72 °C
In this toy environment, including commands that have not yet taken effect can reduce error. This demonstrates a human-designed difference in representation; whether an AI can discover, test, and retain this change on its own requires a separate experiment.
Want to inspect the curves? Take the values for each step and recalculate them.
The questions that matter.
Xiaomai aims for explainable continuous self-evolution. Questioning, research and self-examination are means of accumulating capabilities. Here is what exists today and how the next change would be checked.
Can written reasoning and decomposed computation reveal every cause?
A model's written reasoning is an account to examine, not a complete record of internal computation. Here, explainable AI means checking an explanation against observable inputs, functions, parameters and results, then examining the principles, assumptions and conditions behind them. Equations may omit relationships, and causes may be distributed across mechanisms. Python is the current tool; other basic disciplines or new representations may be needed. What cannot be observed remains unknown.
Why trace what happened before running ablation experiments?
Take the hypothetical example of answering 3 + 5 with 3 × 5 = 15. First trace the request representation, operation selection, calculation and output to identify possible causes. Then decide what to remove, replace or restore. Many mechanisms may be involved; seeing multiplication is not a reason to delete it. A difference after one ablation does not establish a root cause. Compare other candidates and check ordinary addition, multiplication and new situations for damage. This example explains the method; it is not a model result.
Could redefining a problem change the original purpose?
The actual purpose must be preserved. Assumptions, variables, problem representations and research methods can be questioned. If a system always picks easy questions, for example, its selection method may not help it understand the unknown. A human correction may also be wrong; Xiaomai should be able to offer evidence for examination together. Changing a person's purpose requires discussing it with that person, rather than counting an easier replacement goal as success.
How would we know a capability was retained?
First verify that a change entered a problem representation, executable method or model mechanism. Save it, stop the process and reload it. Without reminders of the earlier solution, test a situation held out from tuning, along with existing abilities and computation costs. True has updated and saved 25 research parameter tensors, with matching next updates in two fresh processes. That validates continuation within a limited scope; it does not yet demonstrate improved capability. Autonomous problem formation, validated new knowledge and lasting research capabilities require separate evaluation.
How do the illustrations relate to real model work?
The mechanical body, component relationships and research scenarios are interactive illustrations, not connected to the Xiaomai model. The body represents computational mechanisms. Real engineering work is listed in Research Progress, including True parameter updates, saving and continuation in fresh processes. Tool candidates in this batch were supplied by the host program; no ablation or intervention-reversal experiment was performed. Each record states what was actually validated. The illustrated autonomous research process remains to be tested.
What should a potential collaborator or investor review first?
Start with the public progress records and downloadable research brief. Use its material index to choose a piece of work: timing and GPU integration in the real True workflow, checking observation coverage, or independently reviewing updates and checkpoint continuation. Existing source, tests, comparison tools and handoff records can be requested for review. The site currently publishes summaries and the brief; model weights, raw numerical data and checkpoints require separate authorization, and reproduction needs a matching environment. I am pursuing Xiaomai independently. Scope, deliverables, budget, timing and rights to results can be discussed against that work. The zeczec proposal is under review, scheduled for October 19, 2026 at 12:00 through December 18 at 00:00, Taiwan time, subject to platform approval. Fundraising has not yet launched and payments have not launched.
Privacy & website use
This website has no accounts or payment processing and does not use advertising trackers or website analytics cookies. The interactive illustrations compute in your browser. Research summaries come from a public API on this website; no personal model prompts are transmitted. The collaboration form only prepares an email draft or a text download. It does not store your submission on the website server. If you send the email, your email service and Gmail process it for replies and collaboration discussions. Please do not submit sensitive information. To request deletion of information you have emailed, contact us.
The hosting provider may process necessary connection logs for security and operations. The website developer has not added third-party tracking integrations. Research content may change; capability claims remain limited to each version’s verified scope. Website updated: 2026-10-26. Research-summary dates are shown in the public records.